*本文原为英文写作,中文翻译由 ChatGPT 完成,原貌呈现,少数歧义处标注更正(红色黄色部分)。英文原稿见附录。笔者发现 ChatGPT 翻译不妥处,往往是本人才疏英文原稿表达不够流畅,感兴趣的读者请对照阅读。
ChatGPT 最近引起了研究界、商业界和普通公众的关注。它是一个通用的聊天机器人,可以回答用户的开放式提示或问题。人们对它卓越的、类似于人类的语言技能产生了好奇心,它能够提供连贯、一致和结构良好的回答。由于拥有一个大型的预训练生成式语言模型,它的多轮对话交互支持各种基于文本和代码的任务,包括新颖创作、文字游戏和甚至通过代码生成进行机器人操纵。这使得公众相信通用机器学习和机器理解很快就能实现。
如果深入挖掘,人们可能会发现,当编程代码被添加为训练数据时,模型达到特定规模时,某些推理能力、常识理解甚至思维链(一系列中间推理步骤)可能涌现出来。虽然这个新发现令人兴奋,为人工智能研究和应用开辟了新的可能性,但它引发的问题比解决的问题更多。例如,这些新兴涌现的能力能否作为高级智能的早期指标,或者它们只是幼稚模仿人类行为?继续扩展已经庞大的模型能否导致通用人工智能(AGI)的诞生,还是这些模型只是表面上具有受限能力的人工智能?如果这些问题得到回答,可能会引起人工智能理论和应用的根本性转变。
因此,我们敦促不仅要复制 ChatGPT 的成功,更重要的是在以下人工智能领域推动开创性研究和新的应用开发(这并不是详尽列表):
1.新的机器学习理论,超越了基于任务的特定机器学习的既定范式
归纳推理是一种推理类型,我们根据过去的观察来得出关于世界的结论。机器学习可以被松散地看作是归纳推理,因为它利用过去(训练)数据来提高在新任务上的表现。以机器翻译为例,典型的机器学习流程包括以下四个主要步骤:
1.定义具体问题,例如需要将英语句子翻译成中文:E → C,
2.收集数据,例如句子对 {E → C},
3.训练模型,例如使用输入 {E} 和输出 {C} 的深度神经网络,
4.将模型应用于未知数据点,例如输入一个新的英语句子 E’,输出中文翻译 C’ 并评估结果。
如上所示,传统机器学习将每个特定任务的训练隔离开来。因此,对于每个新任务,必须从步骤 1 到步骤 4 重置并重新执行该过程,失去了来自先前任务的所有已获得的知识(数据、模型等)。例如,如果要将法语翻译成中文,则需要不同的模型。
在这种范式下,机器学习理论家的工作主要集中在理解学习模型从训练数据到未见测试数据的泛化能力。例如,一个常见的问题是在训练中需要多少样本才能实现预测未见测试数据的某个误差界限。我们知道,归纳偏差偏置(即先验知识或先验假设)是学习模型预测其未遇到的输出所必需的。这是因为在未知情况下的输出值完全是任意的,如果不进行一定的假设,就不可能解决这个问题。著名的没有免费午餐定理进一步说明,任何归纳偏差都有局限性;它只适用于某些问题组,如果所假设的先验知识不正确,它可能在其他地方失败。
☞☞☞AI 智能聊天, 问答助手, AI 智能搜索, 免费无限量使用 DeepSeek R1 模型☜☜☜
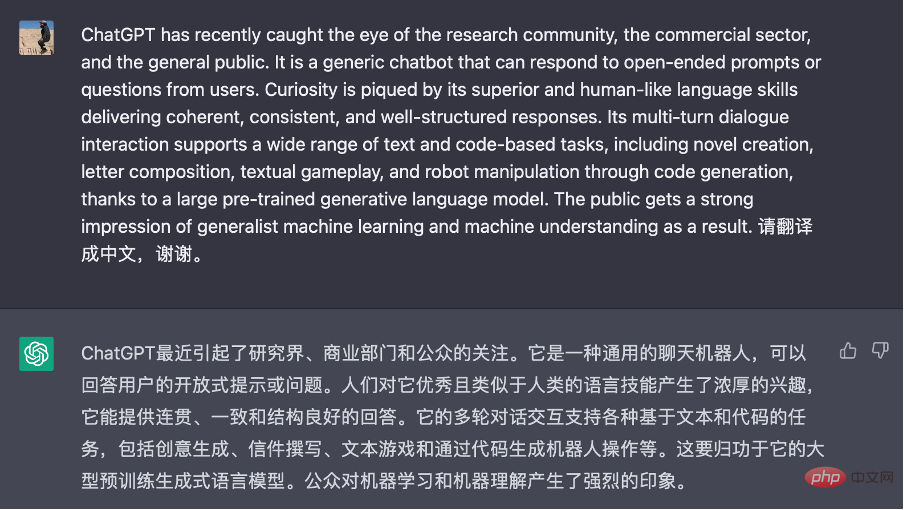
图 1 ChatGPT 用于机器翻译的屏幕截图。用户提示信息仅包含说明,无需演示示例。
虽然上述理论仍然适用,但基础语言模型的出现可能改变了我们对机器学习的方法。新的机器学习流程可以如下(以机器翻译问题为例,见图 1):
1.API 访问其他人训练的基础语言模型,例如训练有包括英语 / 中文配对语料在内的多样文档的模型。
2.根据少量示例或没有示例,为手头任务设计合适的文本描述(称为提示),例如提示Prompt = {几个示例 E ➔ C}。
3.在提示和给定的新测试数据点的条件下,语言模型生成答案,例如将 E’ 追加到提示中并从模型中生成 C’。
4.将答案解释为预测结果。
如步骤 1 所示,基础语言模型作为一个通用一刀切的知识库。步骤 2 中提供的提示和上下文使基础语言模型可以根据少量演示实例自定义以解决特定的目标或问题。虽然上述流程主要局限于基于文本的问题,但可以合理地假设,随着跨模态(见第 3 节)基础预训练模型的发展,它将成为机器学习的标准。这可能会打破必要的任务障碍,为通用人工智能(AGI) 铺平道路。
但是,确定提示文本中演示示例的操作方式仍处于早期阶段。从一些早期的工作中,我们现在理解到,演示样本的格式比标签的正确性更重要(例如,如图 1 所示,我们不需要提供翻译示例,但只需要提供语言说明),但它的可适应性是否有理论上的限制,如 “没有免费的午餐” 定理所述?提示中陈述的上下文和指令式的知识能否集成到模型中以供未来使用?这些问题只是开始探讨。因此,我们呼吁对这种新形式的上下文学习及其理论限制和性质进行新的理解和新的原则,例如研究泛化的界限在哪里。
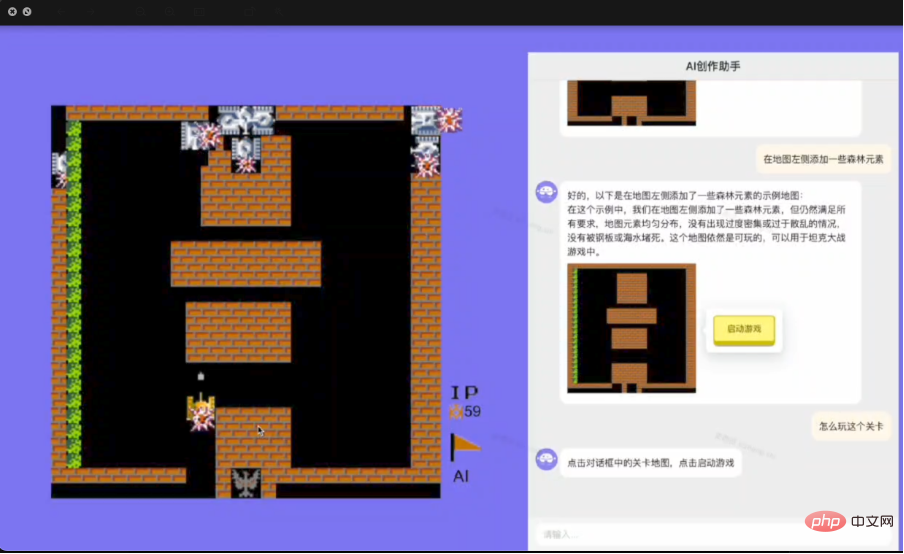
图 2 人工智能决策生成(AIGA)用于设计计算机游戏的插图。
2.磨练推理技能
我们正处于一个令人兴奋的时代边缘,在这个时代里,我们所有的语言和行为数据都可以被挖掘出来,用于训练(并被巨大的计算机化模型吸收)。这是一个巨大的成就,因为我们整个集体的经验和文明都可以消化成一个(隐藏的)知识库(以人工神经网络的形式),以供日后使用。实际上,ChatGPT 和大型基础模型被认为展示了某种形式的推理能力,甚至可能在某种程度上理解他人的心态(心智理论)。这是通过数据拟合(将掩码语言标记预测作为训练信号)和模仿(人类行为)来实现的。然而,这种完全基于数据驱动的策略是否会带来更大的智能还有待商榷。
为了说明这个观点,以指导一个代理(智能体)如何下棋为例。即使代理(智能体)可以访问无限量的人类下棋数据,仅通过模仿现有策略来生成比已有数据更优的新策略将是非常困难的。但是,使用这些数据,可以建立对世界的理解(例如,游戏规则),并将其用于 “思考”(在其大脑中构建一个模拟器,以收集反馈来创建更优的策略)。这突显了归纳偏置的重要性;与其单纯地采用蛮力方法,要求学习代理(智能体)具有一定的世界模型以便自我改进。
因此,迫切需要深入研究和理解基础模型的新兴能力。除了语言技能,我们主张通过研究底层机制来获得实际推理能力。一个有前途的方法是从神经科学和脑科学中汲取灵感,以解密人类推理的机制,并推进语言模型的发展。同时,建立一个扎实的心智理论可能也需要深入了解多智能体学习及其基本原理。
3.从 AI 生成内容(AIGC)到 AI 生成行动(AIGA)
人类语言所发展出的隐式语义对于基础语言模型来说至关重要。如何利用它是通用机器学习的一个关键话题。例如,一旦语义空间与其他媒体(如照片、视频和声音)或其他形式的人类和机器行为数据(如机器人轨迹 / 动作)对齐,我们就可以无需额外成本地为它们获得语义解释能力。这样,机器学习(预测、生成和决策)就会变得通用和可分解。然而,处理跨模态对齐是我们面临的一个重大难题,因为标注关系需要耗费大量的人力。此外,当许多利益方存在冲突时,人类价值观的对齐变得困难。
ChatGPT 的一个基本缺点是它只能直接与人类进行交流。然而,一旦与外部世界建立了足够的对齐,基础语言模型应该能够学习如何与各种各样的参与者和环境进行交互。这很重要,因为它将赋予其推理能力和基于语言的语义更广泛的应用和能力,超越了仅仅进行对话。例如,它可以发展成为一个通用代理(智能体),能够浏览互联网、控制计算机和操纵机器人。因此,更加重要的是实施确保代理(智能体)的响应(通常以生成的操作形式)安全、可靠、无偏和可信的程序。
图 2 展示了 AIGA 与游戏引擎交互的示例,以自动化设计电子游戏的过程。
4.多智能体与基础语言模型交互的理论
ChatGPT 使用上下文学习和提示工程来在单个会话中驱动与人的多轮对话,即给定问题或提示,整个先前的对话(问题和回答)被发送到系统作为额外的上下文来构建响应。这是一个简单的对话驱动的马尔可夫决策过程(MDP)模型:
{状态 = 上下文,行动 = 响应,奖励 = 赞 / 踩评级}。
虽然有效,但这种策略具有以下缺点:首先,提示只是提供了用户响应的描述,但用户真正的意图可能没有被明确说明,必须被推断。也许一个强大的模型,如之前针对对话机器人提出的部分可观察马尔可夫决策过程(POMDP),可以准确地建模隐藏的用户意图。
其次,ChatGPT 首先以拟合语言的生成为目标使用语言适应性进行训练,然后使用人类标签进行对话目标的训练 / 微调。由于平台的开放性质,实际用户的目标和目的可能与训练 / 微调的奖励不一致。为了检查人类和代理(智能体)之间的均衡和利益冲突,使用博弈论的视角可能是值得的。
5.新型应用
正如 ChatGPT 所证明的那样,我们相信基础语言模型具有两个独特的特点,它们将成为未来机器学习和基础语言模型应用的推动力。第一个是其优越的语言技能,而第二个是其嵌入的语义和早期推理能力(以人类语言形式存在)。作为接口,前者将极大地降低应用机器学习的入门门槛,而后者将显著地推广机器学习的应用范围。
如第 1 部分介绍的新学习流程所示,提示和上下文学习消除了数据工程的瓶颈以及构建和训练模型所需的工作量。此外,利用推理能力可以使我们自动分解和解决困难任务的每个子任务。因此,它将大大改变许多行业和应用领域。在互联网企业中,基于对话的界面是网络和移动搜索、推荐系统和广告的明显应用。然而,由于我们习惯于基于关键字的 URL 倒排索引搜索系统,改变并不容易。人们必须被重新教导使用更长的查询和自然语言作为查询。此外,基础语言模型通常是刻板和不灵活的。它们缺乏关于最近事件的当前信息。它们通常会幻想事实,并不提供检索能力和验证。因此,我们需要一种能够随着时间动态演化的即时基础模型。
因此,我们呼吁开发新的应用程序,包括但不限于以下领域:
创新新颖的提示工程、流程和软件支持。基于模型的网络搜索、推荐和广告生成;面向对话广告的新商业模式。针对基于对话的 IT 服务、软件系统、无线通信(个性化消息系统)和客户服务系统的技术。从基础语言模型生成机器人流程自动化(RPA)和软件测试和验证。AI 辅助编程。面向创意产业的新型内容生成工具。将语言模型与运筹学运营研究、企业智能和优化统一起来。在云计算中高效且具有成本效益地服务大型基础模型的方法。针对强化学习、多智能体学习和其他人工智能决策制定领域的基础模型。语言辅助机器人技术。针对组合优化、电子设计自动化(EDA) 和芯片设计的基础模型和推理。
作者简介
汪军,伦敦大学学院(UCL)计算机系教授,上海数字大脑研究院联合创始人、院长,主要研究决策智能及大模型相关,包括机器学习、强化学习、多智能体,数据挖掘、计算广告学、推荐系统等。已发表 200 多篇学术论文,出版两本学术专著,多次获得最佳论文奖,并带领团队研发出全球首个多智能体决策大模型和全球第一梯队的多模态决策大模型。
 AppMall应用商店
AI应用商店,提供即时交付、按需付费的人工智能应用服务
 56 查看详情

Appendix:
Call for Innovation: Post-ChatGPT Theories of Artificial General Intelligence and Their Applications
ChatGPT has recently caught the eye of the research community, the commercial sector, and the general public. It is a generic chatbot that can respond to open-ended prompts or questions from users. Curiosity is piqued by its superior and human-like language skills delivering coherent, consistent, and well-structured responses. Its multi-turn dialogue interaction supports a wide range of text and code-based tasks, including novel creation, letter composition, textual gameplay, and even robot manipulation through code generation, thanks to a large pre-trained generative language model. This gives the public faith that generalist machine learning and machine understanding are achievable very soon.
If one were to dig deeper, they may discover that when programming code is added as training data, certain reasoning abilities, common sense understanding, and even chain of thought (a series of intermediate reasoning steps) may appear as emergent abilities [1] when models reach a particular size. While the new finding is exciting and opens up new possibilities for AI research and applications, it, however, provokes more questions than it resolves. Can these emergent abilities, for example, serve as an early indicator of higher intelligence, or are they simply naive mimicry of human behaviour hidden by data? Would continuing the expansion of already enormous models lead to the birth of artificial general intelligence (AGI), or are these models simply superficially intelligent with constrained capability? If answered, these questions may lead to fundamental shifts in artificial intelligence theory and applications.
We therefore urge not just replicating ChatGPT’s successes but most importantly, pushing forward ground-breaking research and novel application development in the following areas of artificial intelligence (by no means an exhaustive list):
1.New machine learning theory that goes beyond the established paradigm of task-specific machine learning
Inductive reasoning is a type of reasoning in which we draw conclusions about the world based on past observations. Machine learning can be loosely regarded as inductive reasoning in the sense that it leverages past (training) data to improve performance on new tasks. Taking machine translation as an example, a typical machine learning pipeline involves the following four major steps:
1.define the specific problem, e.g., translating English sentences to Chinese: E→C,
2.collect the data, e.g., sentence pairs { E→C },
3.train a model, e.g., a deep neural network with inputs {E} and outputs {C},
4.apply the model to an unseen data point, e.g., input a new English sentence E’ and output a Chinese translation C’ and evaluate the result.
As shown above, traditional machine learning isolates the training for each specific task. Hence, for each new task, one must reset and redo the process from step 1 to step 4, losing all acquired knowledge (data, models, etc.) from previous tasks. For instance, you would need a different model if you want to translate French into Chinese, rather than English to Chinese.
Under this paradigm, the job of machine learning theorists is focused chiefly on understanding the generalisation ability of a learning model from the training data to the unseen test data [2, 3]. For instance, a common question would be how many samples we need in training to achieve a certain error bound of predicting unseen test data. We know that inductive bias (i.e.prior knowledge or prior assumption) is required for a learning model to predict outputs that it has not encountered. This is because the output value in unknown circumstances is completely arbitrary, making it impossible to address the problem without making certain assumptions. The celebrated no-free-lunch theorem [5] further says that any inductive bias has a limitation; it is only suitable for a certain group of problems, and it may fail elsewhere if the prior knowledge assumed is incorrect.
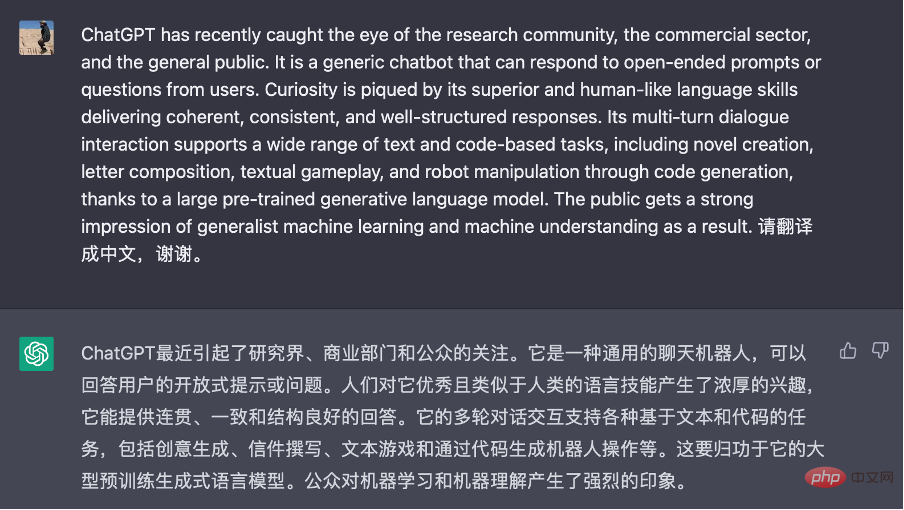
Figure 1 A screenshot of ChatGPT used for machine translation. The prompt contains instruction only, and no demonstration example is necessary.
While the above theories still hold, the arrival of foundation language models may have altered our approach to machine learning. The new machine learning pipeline could be the following (using the same machine translation problem as an example; see Figure 1):
1.API access to a foundation language model trained elsewhere by others, e.g., a model trained with diverse documents, including paring corpus of English/Chinese,
2.with a few examples or no example at all, design a suitable text description (known as a prompt) for the task at hand, e.g., Prompt = {a few examples E→C },
3.conditioned on the prompt and a given new test data point, the language model generates the answer, e.g., append E’ to the prompt and generate C’ from the model,
4.interpret the answer as the predicted result.
As shown in step 1, the foundation language model serves as a one-size-fits-all knowledge repository. The prompt (and context) presented in step 2 allow the foundation language model to be customised to a specific goal or problem with only a few demonstration instances. While the aforementioned pipeline is primarily limited to text-based problems, it is reasonable to assume that, as the development of cross-modality (see Section 3) foundation pre-trained models continues, it will become the standard for machine learning in general. This could break down the necessary task barriers to pave the way for AGI.
But, it is still early in the process of determining how the demonstration examples in a prompt text operate. Empirically, we now understand, from some early work [2], that the format of demonstration samples is more significant than the correctness of the labels (for instance, as illustrated in Figure 1, we don’t need to provide example translation but are required to provide language instruction), but are there any theoretical limits to its adaptability as stated in the no-free-lunch theorem? Can the context and instruction-based knowledge stated in prompts (step 2) be integrated into the model for future usage? We’re only scratching the surface with these inquiries. We therefore call for a new understanding and new principles behind this new form of in-context learning and its theoretical limitations and properties, such as generalisation bounds.
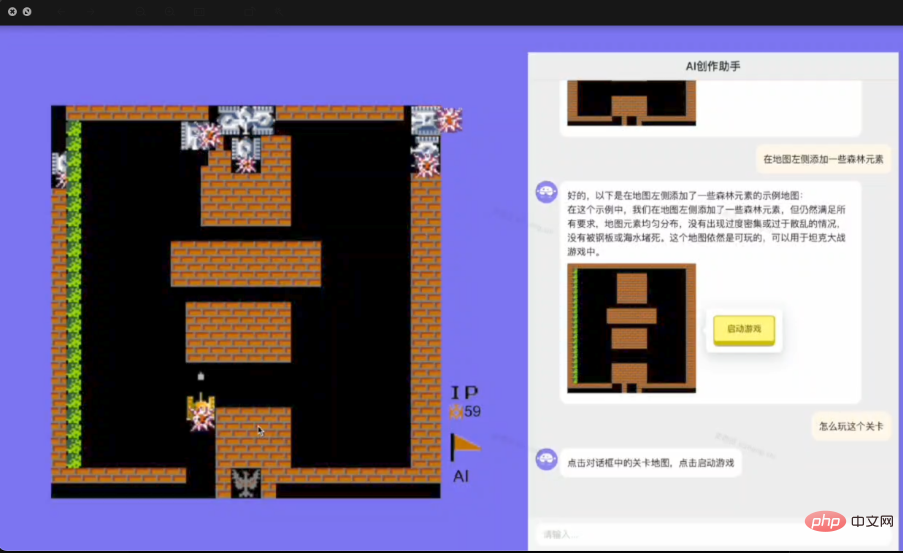
Figure 2 An illustration of AIGA for designing computer games.
2.Developing reasoning skills
We are on the edge of an exciting era in which all our linguistic and behavioural data can be mined to train (and be absorbed by) an enormous computerised model. It is a tremendous accomplishment as our whole collective experience and civilisation could be digested into a single (hidden) knowledge base (in the form of artificial neural networks) for later use. In fact, ChatGPT and large foundation models are said to demonstrate some form of reasoning capacity. They may even arguably grasp the mental states of others to some extent (theory of mind) [6]. This is accomplished by data fitting (predicting masked language tokens as training signals) and imitation (of human behaviours). Yet, it is debatable if this entirely data-driven strategy will bring us greater intelligence.
To illustrate this notion, consider instructing an agent how to play chess as an example. Even if the agent has access to a limitless amount of human play data, it will be very difficult for it, by only imitating existing policies, to generate new policies that are more optimal than those already present in the data. Using the data, one can, however, develop an understanding of the world (e.g., the rules of the game) and use it to “think” (construct a simulator in its brain to gather feedback in order to create more optimal policies). This highlights the importance of inductive bias; rather than simple brute force, a learning agent is demanded to have some model of the world and infer it from the data in order to improve itself.
Thus, there is an urgent need to thoroughly investigate and understand the emerging capabilities of foundation models. Apart from language skills, we advocate research into acquiring of actual reasoning ability by investigating the underlying mechanisms [9]. One promising approach would be to draw inspiration from neuroscience and brain science to decipher the mechanics of human reasoning and advance language model development. At the same time, building a solid theory of mind may also necessitate an in-depth knowledge of multiagent learning [10,11] and its underlying principles.
3.From AI Generating Content (AIGC) to AI Generating Action (AIGA)
The implicit semantics developed on top of human languages is integral to foundation language models. How to utilise it is a crucial topic for generalist machine learning. For example, once the semantic space is aligned with other media (such as photos, videos, and sounds) or other forms of data from human and machine behaviours, such as robotic trajectory/actions, we acquire semantic interpretation power for them with no additional cost [7, 14]. In this manner, machine learning (prediction, generation, and decision-making) would be generic and decomposable. Yet, dealing with cross-modality alignment is a substantial hurdle for us due to the labour-intensive nature of labelling the relationships. Additionally, human value alignment becomes difficult when numerous parties have conflicting interests.
A fundamental drawback of ChatGPT is that it can communicate directly with humans only. Yet, once a sufficient alignment with the external world has been established, foundation language models should be able to learn how to interact with various parties and environments [7, 14]. This is significant because it will bestow its power on reasoning ability and semantics based on language for broader applications and capabilities beyond conversation. For instance, it may evolve into a generalist agent capable of navigating the Internet [7], controlling computers [13], and manipulating robots [12]. Thus, it becomes more important to implement procedures that ensure responses from the agent (often in the form of generated actions) are secure, reliable, unbiased, and trustworthy.
Figure 2 provides a demonstration of AIGA [7] for interacting with a game engine to automate the process of designing a video game.
4.Multiagent theories of interactions with foundation language models
ChatGPT uses in-context learning and prompt engineering to drive multi-turn dialogue with people in a single session, i.e., given the question or prompt, the entire prior conversation (questions and responses) is sent to the system as extra context to construct the response. It is a straightforward Markov decision process (MDP) model for conversation:
{State = context, Action = response, Reward = thumbs up/down rating}.
While effective, this strategy has the following drawbacks: first, a prompt simply provides a description of the user’s response, but the user’s genuine intent may not be explicitly stated and must be inferred. Perhaps a robust model, as proposed previously for conversation bots, would be a partially observable Markov decision process (POMDP) that accurately models a hidden user intent.
Second, ChatGPT is first trained using language fitness and then human labels for conversation goals. Due to the platform’s open-ended nature, actual user’s aim and objective may not align with the trained/fined-tuned rewards. In order to examine the equilibrium and conflicting interests of humans and agents, it may be worthwhile to use a game-theoretic perspective [9].
5.Novel applications
As proven by ChatGPT, there are two distinctive characteristics of foundation language models that we believe will be the driving force behind future machine learning and foundation language model applications. The first is its superior linguistic skills, while the second is its embedded semantics and early reasoning abilities (in the form of human language). As an interface, the former will greatly lessen the entry barrier to applied machine learning, whilst the latter will significantly generalise how machine learning is applied.
As demonstrated in the new learning pipeline presented in Section 1, prompts and in-context learning eliminate the bottleneck of data engineering and the effort required to construct and train a model. Moreover, exploiting the reasoning capabilities could enable us to automatically dissect and solve each subtask of a hard task. Hence, it will dramatically transform numerous industries and application sectors. In internet-based enterprises, the dialogue-based interface is an obvious application for web and mobile search, recommender systems, and advertising. Yet, as we are accustomed to the keyword-based URL inverted index search system, the change is not straightforward. People must be retaught to utilise longer queries and natural language as queries. In addition, foundation language models are typically rigid and inflexible. It lacks access to current information regarding recent events. They typically hallucinate facts and do not provide retrieval capabilities and verification. Thus, we need a just-in-time foundation model capable of undergoing dynamic evolution over time.
We therefore call for novel applications including but not limited to the following areas:
Novel prompt engineering, its procedure, and software support.Generative and model-based web search, recommendation and advertising; novel business models for conversational advertisement.Techniques for dialogue-based IT services, software systems, wireless communications (personalised messaging systems) and customer service systems.Automation generation from foundation language models for Robotic process automation (RPA) and software test and verification.AI-assisted programming.Novel content generation tools for creative industries.Unifying language models with operations research and enterprise intelligence and optimisation.Efficient and cost-effective methods of serving large foundation models in Cloud computing. Foundation models for reinforcement learning and multiagent learning and, other decision-making domains.Language-assisted Robotics.Foundation models and reasoning for combinatorial optimisation, EDA and chip design.
以上就是”创新呼声:UCL汪军探讨ChatGPT通用人工智能理论及应用前景”的详细内容,更多请关注创想鸟其它相关文章!
版权声明:本文内容由互联网用户自发贡献,该文观点仅代表作者本人。本站仅提供信息存储空间服务,不拥有所有权,不承担相关法律责任。
如发现本站有涉嫌抄袭侵权/违法违规的内容, 请发送邮件至 chuangxiangniao@163.com 举报,一经查实,本站将立刻删除。
发布者:程序猿,转转请注明出处:https://www.chuangxiangniao.com/p/555542.html
 微信扫一扫
 支付宝扫一扫