随着音频内容消费的日益普及,将文档或书面内容转换为真实音频格式的能力最近已成为趋势。
虽然 google 的 notebooklm 在这个领域引起了人们的关注,但我想探索使用现代云服务构建一个类似的系统。在本文中,我将向您介绍如何创建一个可扩展的云原生系统,该系统使用 fastapi、firebase、google cloud pub/sub 和 azure 的文本转语音服务将文档转换为高质量的播客。
这里有一个展示,您可以参考该系统的结果:mypodify showcase
挑战
将文档转换为播客并不像通过文本转语音引擎运行文本那么简单。它需要仔细的处理、自然语言的理解以及处理各种文档格式的能力,同时保持流畅的用户体验。系统需要:
高效处理多种文档格式生成具有多种声音的自然声音音频应对大规模文档处理而不影响用户体验为用户提供实时状态更新保持高可用性和可扩展性
架构深度探究
让我们分解关键组件并了解它们如何协同工作:
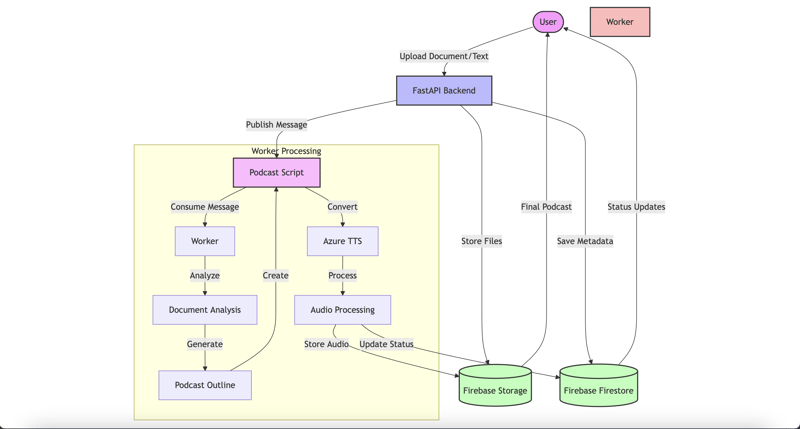
1.fastapi后端
fastapi 作为我们的后端框架,选择它有几个令人信服的原因:
异步支持:fastapi 的异步功能构建于 starlette 之上,可有效处理并发请求自动 openapi 文档:生成开箱即用的交互式 api 文档类型安全:利用 python 的类型提示进行运行时验证高性能:速度可与 node.js 和 go 相媲美
这是我们的上传端点的详细信息:
@app.post('/upload')async def upload_files( token: annotated[parsedtoken, depends(verify_firebase_token)], project_name: str, description: str, website_link: str, host_count: int, files: optional[list[uploadfile]] = file(none)): # validate token user_id = token['uid'] # generate unique identifiers project_id = str(uuid.uuid4()) podcast_id = str(uuid.uuid4()) # process and store files file_urls = await process_uploads(files, user_id, project_id) # create firestore document await create_project_document(user_id, project_id, { 'status': 'pending', 'created_at': datetime.now(), 'project_name': project_name, 'description': description, 'file_urls': file_urls }) # trigger async processing await publish_to_pubsub(user_id, project_id, podcast_id, file_urls) return {'project_id': project_id, 'status': 'processing'}
2.firebase集成
firebase 为我们的应用程序提供了两项关键服务:
firebase 存储
通过自动缩放处理安全文件上传为生成的音频文件提供 cdn 支持的分发支持大文件断点续传
火库
用于项目状态跟踪的实时数据库基于文档的结构非常适合项目元数据自动缩放,无需手动分片
以下是我们实现实时状态更新的方法:
async def update_status(user_id: str, project_id: str, status: str, metadata: dict = none): doc_ref = db.collection('projects').document(f'{user_id}/{project_id}') update_data = { 'status': status, 'updated_at': datetime.now() } if metadata: update_data.update(metadata) await doc_ref.update(update_data)
3. 谷歌云发布/订阅
pub/sub 作为我们的消息传递主干,支持:
解耦架构以实现更好的可扩展性至少一次交货保证自动消息保留和重放失败消息的死信队列
消息结构示例:
{ 'user_id': 'uid_123', 'project_id': 'proj_456', 'podcast_id': 'pod_789', 'file_urls': ['gs://bucket/file1.pdf'], 'description': 'technical blog post about cloud architecture', 'host_count': 2, 'action': 'create_project'}
4. 使用 azure 语音服务生成语音
我们音频生成的核心使用 azure 的认知服务语音 sdk。让我们看看我们如何实现听起来自然的语音合成:
import azure.cognitiveservices.speech as speechsdkfrom pathlib import pathclass speechgenerator: def __init__(self): self.speech_config = speechsdk.speechconfig( subscription=os.getenv("azure_speech_key"), region=os.getenv("azure_speech_region") ) async def create_speech_segment(self, text, voice, output_file): try: self.speech_config.speech_synthesis_voice_name = voice synthesizer = speechsdk.speechsynthesizer( speech_config=self.speech_config, audio_config=none ) # generate speech from text result = synthesizer.speak_text_async(text).get() if result.reason == speechsdk.resultreason.synthesizingaudiocompleted: with open(output_file, "wb") as audio_file: audio_file.write(result.audio_data) return true return false except exception as e: logger.error(f"speech synthesis failed: {str(e)}") return false
我们系统的独特功能之一是能够使用人工智能生成多语音播客。以下是我们如何处理不同主机的脚本生成:
async def generate_podcast_script(outline: str, analysis: str, host_count: int): # system instructions for different podcast formats system_instructions = two_host_system_prompt if host_count > 1 else one_host_system_prompt # example of how we structure the ai conversation if host_count > 1: script_format = """ **alex**: "hello and welcome to mypodify! i'm your host alex, joined by..." **jane**: "hi everyone! i'm jane, and today we're diving into {topic}..." """ else: script_format = """ **alex**: "welcome to mypodify! today we're exploring {topic}..." """ # generate the complete script using ai script = await generate_content_from_openai( content=f"{outline}nncontent details:{analysis}", system_instructions=system_instructions, purpose="podcast script" ) return script
对于语音合成,我们将不同的扬声器映射到特定的 azure 语音:
voice_mapping = { 'alex': 'en-us-andrewmultilingualneural', # male host 'jane': 'en-us-avamultilingualneural', # female host 'narrator': 'en-us-brandonmultilingualneural' # neutral voice}
5. 后台处理工作者
工作组件处理繁重的工作:
文献分析
从各种文档格式中提取文本分析文档结构和内容确定关键主题和部分
内容处理
生成自然的对话流将内容分割成演讲者片段创建主题之间的过渡
音频生成
使用 azure 的神经语音将文本转换为语音处理多个说话者的声音应用音频后处理
这是我们的工作逻辑的简化视图:
async def process_document(message_data: dict): try: # extract content from documents content = await extract_document_content(message_data['file_urls']) # analyze and structure content document_analysis = await analyze_content(content) # generate podcast script script = await generate_script( document_analysis, speaker_count=message_data['host_count'] ) # convert to audio audio_segments = await generate_audio_segments(script) # post-process audio final_audio = await post_process_audio(audio_segments) # upload and update status audio_url = await upload_to_storage(final_audio) await update_status( message_data['user_id'], message_data['project_id'], 'completed', {'audio_url': audio_url} ) except exception as e: await handle_processing_error(message_data, e)
错误处理和可靠性
系统实现了全面的错误处理:
重试逻辑
api 调用失败的指数退避最大重试次数配置失败消息的死信队列
状态追踪
firestore 中存储的详细错误消息向用户实时更新状态监控错误聚合
资源清理
自动删除临时文件上传清理失败孤立资源检测
扩展和性能优化
为了处理生产负载,我们实施了多项优化:
工作人员缩放
基于队列长度的水平扩展基于资源的自动缩放区域部署以降低延迟
存储优化
内容去重压缩音频存储cdn 集成交付
处理优化
类似文档的批量处理缓存重复内容尽可能并行处理
监控和可观察性
系统包括全面监控:
async def track_metrics(stage: str, duration: float, metadata: dict = None): metrics = { 'stage': stage, 'duration_ms': duration * 1000, 'timestamp': datetime.now() } if metadata: metrics.update(metadata) await publish_metrics(metrics)
未来的增强功能
虽然当前系统运行良好,但未来的改进还有一些令人兴奋的可能性:
增强的音频处理
背景音乐整合高级音频效果自定义语音训练
内容增强
自动章节标记互动文字记录多语言支持
平台整合
直接播客平台发布rss feed 生成社交媒体分享
构建文档到播客转换器是现代云架构的一次激动人心的旅程。 fastapi、firebase、google cloud pub/sub 和 azure 的文本转语音服务的组合为大规模处理复杂的文档处理提供了坚实的基础。
事件驱动的架构确保系统在负载下保持响应,而托管服务的使用减少了运营开销。无论您是要构建类似的系统还是只是探索云原生架构,我希望这次深入研究能够为构建可扩展、生产就绪的应用程序提供宝贵的见解。
想了解更多有关云架构和现代应用程序开发的信息吗?关注我,获取更多技术实用教程。
以上就是如何构建您自己的 Google NotebookLM的详细内容,更多请关注创想鸟其它相关文章!
版权声明:本文内容由互联网用户自发贡献,该文观点仅代表作者本人。本站仅提供信息存储空间服务,不拥有所有权,不承担相关法律责任。
如发现本站有涉嫌抄袭侵权/违法违规的内容, 请发送邮件至 chuangxiangniao@163.com 举报,一经查实,本站将立刻删除。
发布者:程序猿,转转请注明出处:https://www.chuangxiangniao.com/p/1354398.html
 微信扫一扫
 支付宝扫一扫